Updating a fleet without breaking it
Updating one vehicle on a bench is trivial. Updating hundreds of vehicles in the field, across firmware versions, configurations and hardware revisions accumulated over years, without turning one of them into a brick, is not.
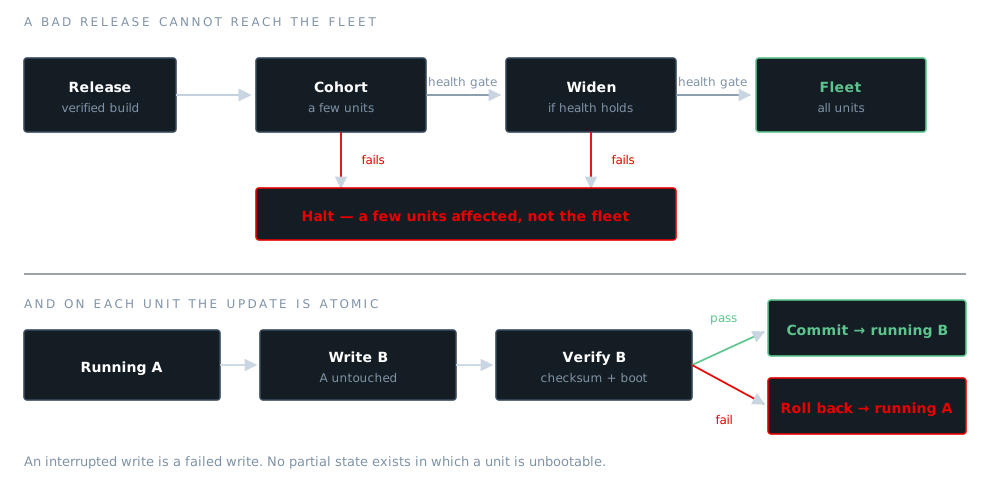
We build update and configuration systems with the failure cases designed first: atomic updates that either complete or roll back, recovery that works when an update is interrupted mid-write, verification that the vehicle is running what the fleet record says, and staged rollout so a bad release reaches a handful of units rather than all of them.
Version alignment as a safety property
A fleet whose members are quietly running different firmware is a fleet whose behaviour cannot be predicted, whose incidents cannot be reproduced and whose certification basis is questionable. We treat knowing exactly what every unit is running as a safety property, and build the tooling that keeps it true.
Predicting failures instead of reacting to them
Components rarely fail without warning; they fail without anyone listening. Motor current signatures drift, cell impedance rises, vibration spectra change, thermal behaviour shifts — usually well before the failure.
We build monitoring that models normal behaviour for each specific airframe and flags departure from it, so maintenance is scheduled against evidence rather than against a calendar or an incident. The aim is a warning several flight hours before the failure, with enough specificity to name the component.
Talk to us about your system
The most useful first message describes the constraint you cannot get past.
Start a conversation